Announcements
Introducing Claude Fable 5.1
Our most capable model for coding and knowledge work, with research capabilities that offer an early glimpse of how AI will soon contribute to scientific progress.
View moreImproving Fable 5’s biology safeguards
We’re making updates to Claude Fable 5’s biology safeguards in a way that substantially reduces false positives.
View moreClaude Fable 5 is rolling out
Access to Claude Fable 5 has been restored. It brings 5th-generation intelligence to your most ambitious coding and professional work.
View moreClaude Fable 5 access unavailable
We apologize for this disruption to our customers and are working to restore access as soon as possible.
View moreClaude Fable 5
Claude Fable 5 introduces our 5th model generation for your most ambitious work. Tackle days-long, complex, and asynchronous tasks previous models couldn’t sustain.
View more
Availability and pricing
For individuals and organizations taking on their hardest knowledge and coding work, Claude Fable 5.1 is available to Pro, Max, Team, and Enterprise users.
For developers interested in building AI solutions that demand frontier intelligence, Claude Fable 5.1 is available on the Claude Platform natively, through available marketplaces, and in Amazon Web Services, Google Cloud, and Microsoft Foundry.
Claude Fable 5.1 is priced at $10 per million input tokens and $50 per million output tokens. Cache reads now cost $0.25 per million tokens, 75% less than Fable 5, which reduces the cost of typical workloads by an estimated 25% and highly agentic workloads by up to approximately 45%. To learn more, check out our pricing page. To get started, use claude-fable-5-1 via the Claude API.
For workloads that need to run in the US, US-only inference is available at 1.1x pricing for input and output tokens. Learn more.
Use cases
Claude Fable 5.1 is a Mythos-level model built for your most ambitious, long-running projects. It avoids easy-seeming shortcuts, fixes the root causes of problems rather than the symptoms, and keeps you updated as it works.
Agents
Claude Fable 5.1 is built for jobs that take hours and span many applications: working through a backlog in Cowork, picking up requests in Slack through Claude Tag (beta), operating a browser, or running unattended as a managed agent on the Claude Platform. It plans the work, uses the tools it needs, recovers when a step fails, and keeps you posted without being asked.
Coding
Claude Fable 5.1 is our most capable model for ambitious coding projects: features that span an entire codebase, code review, performance work, and multi-day autonomous sessions. It can write its own tests to check its work, implement designs with high fidelity, and use vision to check outputs against goals.
Enterprise workflows
Claude Fable 5.1 handles complex, multi-stage knowledge work with minimal oversight, from deep research and analysis to deliverables ready for your review. Teams can hand off large projects and review completed work rather than supervising every step.
Vision
Claude Fable 5.1 understands diagrams, charts, and tables nested in files and PDFs, improving document-heavy work in finance, legal, analytics, and architecture. The model also uses vision to help evaluate its own coding work, checking outputs against the original design or goal.
Safeguards
Claude Fable 5.1 includes robust safeguards for cybersecurity and biology. Many queries in these domains are automatically routed to less capable models if flagged by these safeguards. You won’t be charged Fable prices for rerouted requests. Learn more about how the fallback experience works. Security teams whose legitimate work is affected can apply to the Cyber Verification Program for adjusted safeguards.
We extensively test and evaluate our models in an effort to ensure they meet Anthropic’s standards for safety, security, and reliability. The accompanying system card covers safety results in depth.
Data retention
Using Fable requires 30-day data retention for safety monitoring by default. Enterprise customers eligible for Enterprise Frontier Safeguards can store data on their own cloud infrastructure and any human review is by default done by the customer themselves, rather than Anthropic. Until the phased rollout of EFS is complete, eligible customers receive zero data retention on Fable 5 and Fable 5.1.
Learn more about data retention. Learn more about Enterprise Frontier Safeguards.
Benchmarks
Claude Fable 5.1 sets a new standard on coding, knowledge work, and long-running problem-solving tasks.
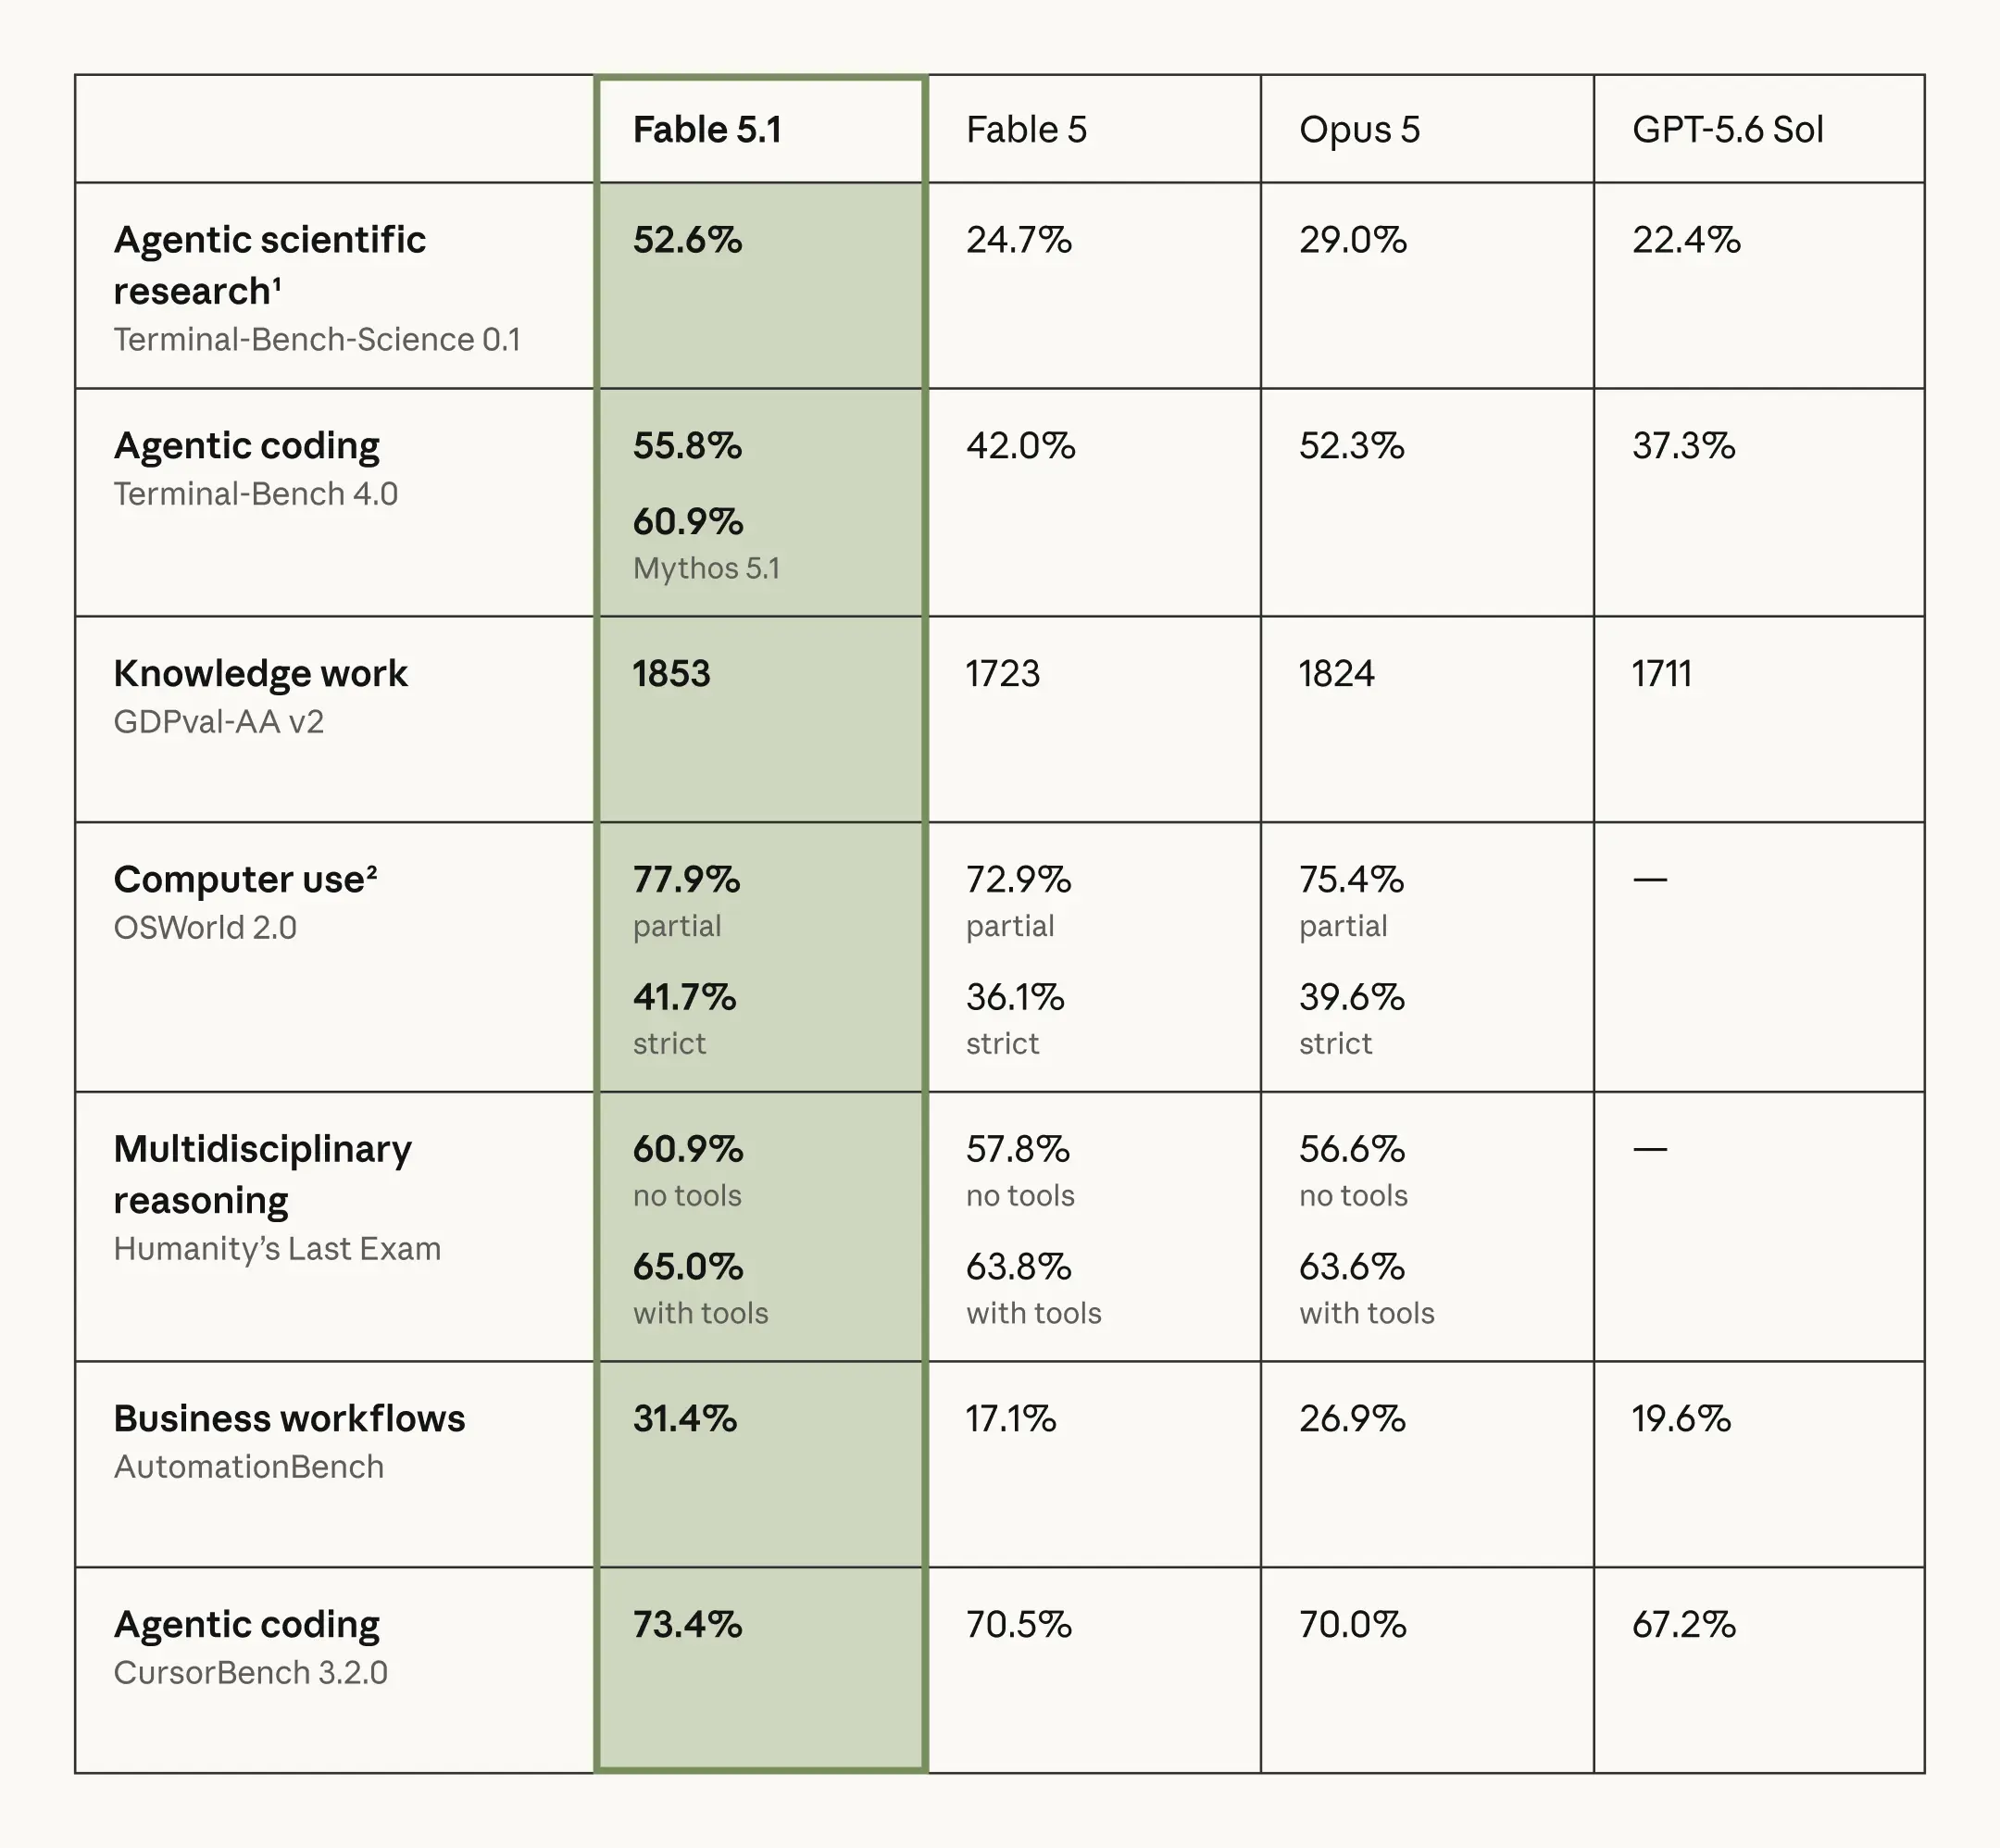
1Terminal-Bench-Science 0.1: The standard error is ±3.5–4.5 pts per model. The public leaderboard (3 trials/task, Claude Code harness) reports Claude Opus 5 at 30.0% and Claude Fable 5 at 21.4%; our setup reproduces them at 29.0% and 24.7%, respectively, both within noise.
2OSWorld 2.0: Scores are on the benchmark authors’ August 2026 task release; Fable 5 and Opus 5 were re-run under the same conditions. Because the task files differ from earlier releases, these numbers aren't directly comparable to previously published OSWorld 2.0 results, which is why no competitor score is shown.
Hear from our customers
“In internal benchmarks, Claude Fable 5.1 solves more of our coding problems than Fable 5 or Opus 5, and achieves state of the art on trading intuition. While prior models became hard to follow the longer they worked, Fable 5.1 remains readable over long, multi-step tasks.”
“We’re moving our Opus 5 traffic in Devin to Claude Fable 5.1 on launch day. It matched or edged out Fable 5 in our testing at a lower cost per task, and with the new cache read pricing a Fable-class model is finally economical for the workloads we’d kept on Opus, starting with code review.”
“A particular piece of code had an extremely rare crash, about one in a million runs, that nobody on our team had explained in four to five years. Every model I tried, including Fable 5, missed it. Claude Fable 5.1 was the first to find it. It disassembled an external vendor library, matched it against the core dump, and traced the crash to a bug in that library. The time it would have taken to conduct that analysis is hard to justify.”
“Claude Fable 5.1 built a complex prototype in about three days. It did initial research across all of our services code and documentation to produce a novel and extensible design. It then ran for hours unattended, with strong verification loops, to implement the entire prototype. I would wake up in the morning to the next phase finished, with a full visual walkthrough of what it built and clear evidence of its success.”
“It’s friendly Fable. Fable-level intelligence, Opus-level price, Sonnet-speed. In our tests it was about twice as fast as Opus 5 and used half as many tokens, so for anyone used to using Opus as their daily driver it’s an obvious upgrade. ”
“On our research suite, Claude Fable 5.1 set new best scores. On one task it came up with a novel solution along a completely different axis than we’d seen from other models or from human researchers in the past, which took its results well above the previous plateau. It's better at creative problem solving and getting that flash of insight you need to solve a difficult problem.”
“As part of our ongoing evaluation of AI models, Claude Fable 5.1 delivered impressive results in our tests. Using Claude Code, it correctly identified the root cause of every broken build we tested, across all the effort levels. It also communicates more effectively than earlier Anthropic models, with updates that are more concise and easier to follow.”
“Claude Fable 5.1 is very smart. On our 30-day simulated run-a-business eval, where the model gets full access to simulated Square tools, customers, employees and vendors, it was far more efficient per token than Opus 5. We plan to use it to work through our most complex scenarios, the kind that used to take days of whiteboarding, so our engineering teams can keep moving fast.”